Predicting Student Academic Performance Using GenAI-Enhanced Deep Learning Features: A Comparative Study
Keywords:
educational data mining; student performance prediction; generative AI; deep learning; CNN-LSTM; FT-Transformer; feature augmentation; grade classificationAbstract
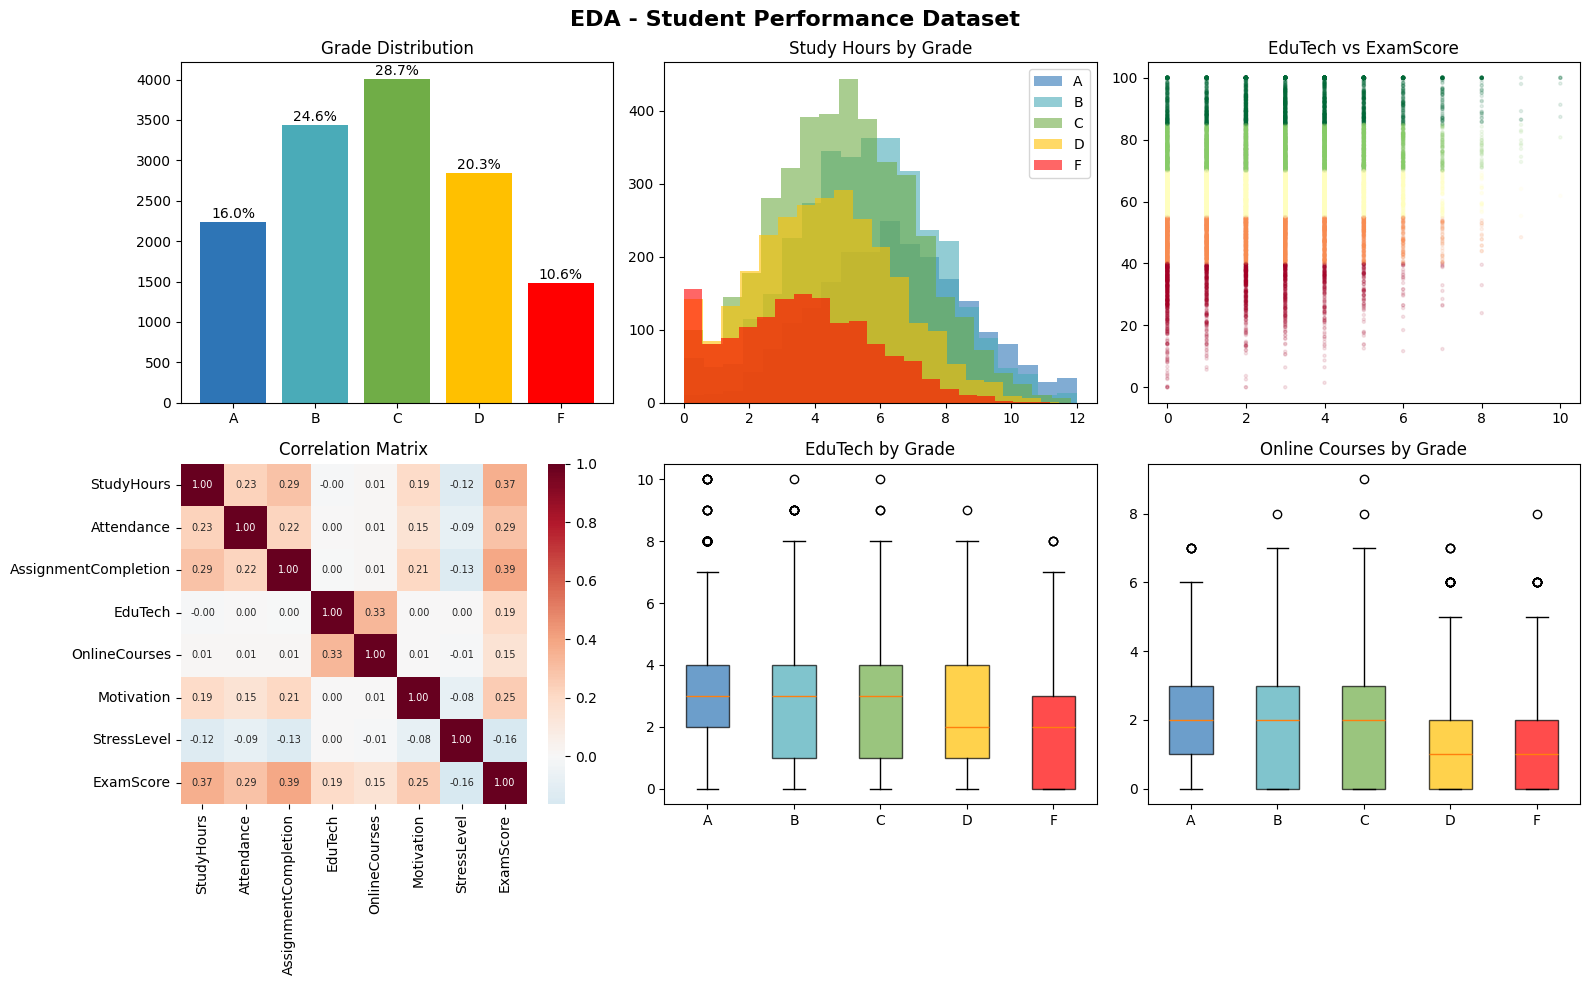
Predicting student academic performance is a critical challenge in educational data mining, with implications for early intervention, personalized learning, and policy-making. This paper evaluates whether Generative AI (GenAI)-derived behavioral and contextual features add predictive value beyond traditional educational attributes for grade classification. We benchmark five deep learning architectures — Residual MLP, Bidirectional LSTM (BiLSTM), CNN with Global Average Pooling (CNN-GAP), Feature Tokenizer Transformer (FT-Transformer), and a Hybrid CNN-LSTM model — together with four gradient-boosted and ensemble baselines (Random Forest, XGBoost, LightGBM, CatBoost), under two feature-set conditions: a Traditional baseline and a Full GenAI-augmented setting. Experiments are conducted on a curated dataset of 14,003 student records with 16 base features spanning study habits, technology use, psycho-social indicators, and learning style, expanded with GenAI-derived engagement, risk, technology-adoption, and support-need scores generated by an open-weight instruction-tuned language model (Qwen2.5-1.5B-Instruct). Contrary to our initial hypothesis, results do not support a general benefit from GenAI feature augmentation: across the nine models tested, only the FT-Transformer shows a statistically significant improvement (+3.3 percentage points, paired t-test, p = 0.0002), while Random Forest shows a significant decline (−0.6 points, p = 0.040); the remaining seven models show small, non-significant shifts in either direction (all p > 0.13). A controlled ablation study using the strongest architecture (Hybrid CNN-LSTM) reinforces this picture: removing the GenAI-derived features entirely (33.01% ± 1.32%) performs marginally better, not worse, than the full feature set (32.76% ± 0.89%), with overlapping error bars. The best absolute performance in the study is achieved by CatBoost on traditional features alone (34.6%), and the strongest overall configuration is a heterogeneous CNN-GAP + CatBoost ensemble (34.4% accuracy, mean AUC 0.665). We report these results transparently, including the negative and null findings, and argue that this architecture-dependent, largely non-significant pattern is itself the useful finding for practitioners considering GenAI-based feature engineering in educational data mining: it is not a reliable, drop-in source of predictive lift, and its value, if any, appears contingent on the specific model architecture used.
References
[1] Romero C, Ventura S. Educational data mining: a review of the state of the art. IEEE Trans Syst Man Cybern Part C Appl Rev. 2010;40:601-618. doi:10.1109/TSMCC.2010.2053532
[2] Baker RS, Inventado PS. Educational data mining and learning analytics. Larusson JA, White B (ed): Learning Analytics: From Research to Practice. Springer, New York, NY; 2014. 61-75. doi:10.1007/978-1-4614-3305-7_4
[3] Dutt A, Ismail MA, Herawan T. A systematic review on educational data mining. IEEE Access. 2017;5:15991-16005. doi:10.1109/ACCESS.2017.2654247
[4] Kotsiantis SB, Pierrakeas C, Pintelas P. Predicting students’ performance in distance learning using machine learning techniques. Appl Artif Intell. 2004;18:411-426. doi:10.1080/08839510490442058
[5] Huang AYQ, Lu OHT, Huang JCH, Yin CJ, Yang SJH. Predicting students’ academic performance by using educational big data and learning analytics: evaluation of classification methods and learning logs. Interact Learn Environ. 2020;28:206-230. doi:10.1080/10494820.2019.1636086
[6] Brown T, Mann B, Ryder N, et al. Language models are few-shot learners. Adv Neural Inf Process Syst. 2020;33:1877-1901. https://arxiv.org/abs/2005.14165
[7] Vaswani A, Shazeer N, Parmar N, et al. Attention is all you need. Adv Neural Inf Process Syst. 2017;30:5998-6008. https://proceedings.neurips.cc/paper/2017/hash/3f5ee243547dee91fbd053c1c4a845aa-Abstract.html
[8] Chawla NV, Bowyer KW, Hall LO, Kegelmeyer WP. SMOTE: synthetic minority over-sampling technique. J Artif Intell Res. 2002;16:321-357. doi:10.1613/jair.953
[9] Akiba T, Sano S, Yanase T, Ohta T, Koyama M. Optuna: a next-generation hyperparameter optimization framework. Proceedings of the 25th ACM SIGKDD International Conference on Knowledge Discovery & Data Mining. 2019;2623-2631. doi:10.1145/3292500.3330701
[10] Lundberg SM, Lee SI. A unified approach to interpreting model predictions. Adv Neural Inf Process Syst. 2017;30:4765-4774. https://proceedings.neurips.cc/paper_files/paper/2017/file/8a20a8621978632d76c43dfd28b67767-Paper.pdf
[11] Hochreiter S, Schmidhuber J. Long short-term memory. Neural Comput. 1997;9:1735-1780. doi:10.1162/neco.1997.9.8.1735
[12] Gorishniy Y, Rubachev I, Khrulkov V, Babenko A. Revisiting deep learning models for tabular data. Adv Neural Inf Process Syst. 2021;34:18932-18943. https://proceedings.neurips.cc/paper/2021/hash/9d86d83f925f2149e9edb0ac3b49229c-Abstract.html
[13] He K, Zhang X, Ren S, Sun J. Deep residual learning for image recognition. Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR). 2016;770-778. doi:10.1109/CVPR.2016.90
[14] Loshchilov I, Hutter F. Decoupled weight decay regularization. International Conference on Learning Representations (ICLR 2019). 2019, https://openreview.net/forum?id=Bkg6RiCqY7
[15] Zhang H, Cisse M, Dauphin YN, Lopez-Paz D. mixup: beyond empirical risk minimization. International Conference on Learning Representations (ICLR 2018). 2018, https://openreview.net/forum?id=r1Ddp1-Rb
Downloads
Published
Data Availability Statement
The Student Academic Performance Dataset, the GenAI feature-generation pipeline, model training code, and analysis scripts that support the findings of this study are available from the corresponding author upon reasonable request.
Issue
Section
License
Copyright (c) 2026 Journal of Intelligent Machines and Engineering

This work is licensed under a Creative Commons Attribution 4.0 International License.